Speech recognition quietly went open-weight — and it fits in 1.56 GB
Alibaba's Qwen3-ASR models are Apache-2.0, cover 52 languages and dialects, and download in under two gigabytes. A plain-language guide to the open-weight transcription layer: what exists, what running a model on your own laptop actually buys you, and where the closed APIs still win.
You can now run open-weight speech recognition on a laptop: Alibaba's Qwen team publishes Qwen3-ASR-0.6B, Qwen3-ASR-1.7B, and the companion Qwen3-ForcedAligner-0.6B under Apache 2.0. The smallest download is 1.56 GB, supports 52 languages and dialects, and, since June 26, can run in three lines of standard Python. Running it on your own machine avoids a per-request transcription bill.
The shift will feel familiar to anyone who followed open language models: self-hosting offers more control over cost, privacy, and offline use, while hosted APIs remain easier to operate. Speech recognition is now developing the same choice, with models small enough to run locally.
This guide explains what open-weight speech recognition does, how the available models and licenses differ, what a small model can run on, and where hosted APIs still have an advantage.
TL;DR:
- Open-weight transcription is real and usable today: Qwen3-ASR (Apache 2.0, 52 languages/dialects), Whisper (MIT), NVIDIA's Parakeet and Canary (CC BY 4.0), Mistral's Voxtral (Apache 2.0).
- Self-hosting buys privacy, offline operation, and cost control. On the independent Artificial Analysis board, hosting an open model runs $1.50 per 1,000 minutes against $6.00 for Microsoft's MAI-Transcribe-1.5 and $18.15 for Gemini 3.1 Pro Preview.
- The number one accuracy spot is still a closed preview endpoint — but an open Apache-2.0 model, Voxtral Small, now sits fifth, about one point of word error rate behind it.
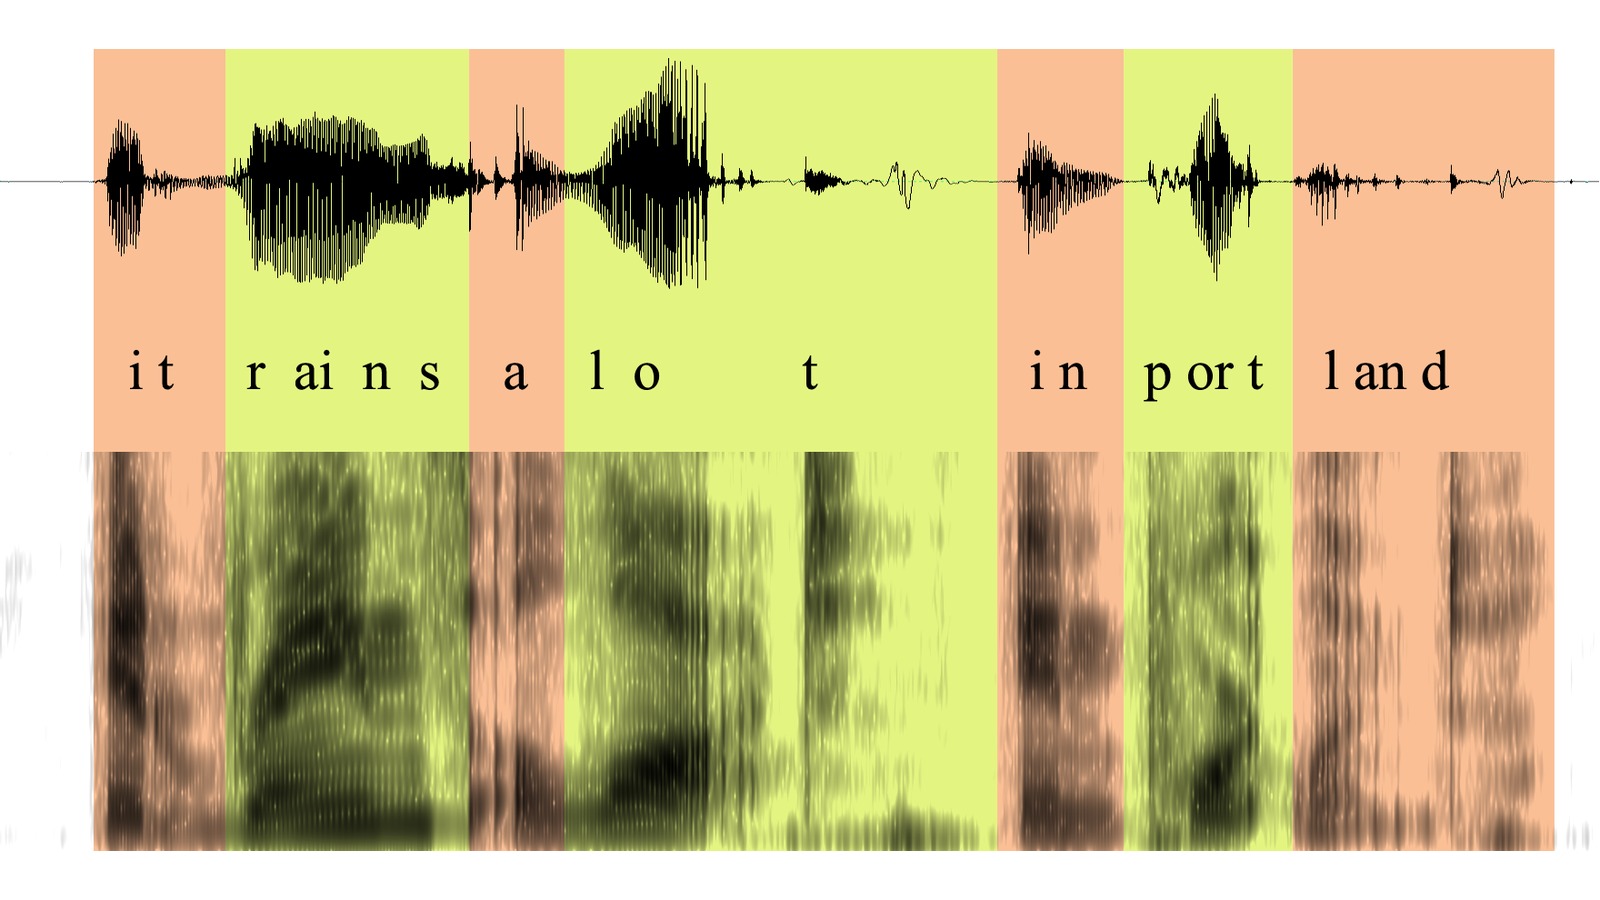
Image: Aaron Parecki, Wikimedia Commons, CC BY 2.0. The waveform and spectrogram of the phrase "it rains a lot in Portland," with the letters positioned over the audio they correspond to — this is the raw material every speech recognition model works from.
What you are actually downloading when you download a transcriber
An ASR model — automatic speech recognition, used interchangeably with STT, speech-to-text — is a program that takes audio in and produces text out. That is the whole job. It does not decide who spoke, does not summarize, does not know what your meeting was about. It hears words and writes them down.
"Open weights" means the lab published the finished model file itself. A model's weights are the enormous grid of numbers it learned during training, and publishing them means you download that file, run it on your own hardware, and build on it without asking permission or paying per request. The alternative is a closed model, where the weights stay on the vendor's servers and you rent access through an API — audio goes up, text comes back, and you are billed by the minute.
The number in the name is the parameter count, and for speech models it is unusually meaningful. "0.6B" means roughly 600 million parameters, which in practice makes Qwen3-ASR-0.6B a 1.56 GB file and Qwen3-ASR-1.7B a 4.08 GB one — both small enough to sit on a laptop SSD without anyone noticing. Compare that to the open language models we covered in our China roundup, where the headline release was 1.56 terabytes across 96 shards and needed a cluster just to load. Speech models are a thousand times smaller than frontier text models, and that single fact is why this shift lands harder here than it did there.
Call this size range the laptop tier: models small enough that trying them becomes a download rather than a hardware-budget decision. Most frontier text models remain outside it; many speech models fit.
Check the license before adopting a model. Apache 2.0 and MIT permit use, modification, and commercial distribution; CC BY 4.0, used by NVIDIA's models, also permits commercial use but requires attribution.
Qwen shipped the family in January; June is when it got easy
Qwen3-ASR first appeared on January 28, 2026, and its technical report followed on arXiv the next day. On June 26, Qwen published -hf versions of all three models, compatible with Hugging Face Transformers v5.13.0 onward.
The packaging change makes setup more familiar: instead of installing Qwen's qwen-asr package or a vLLM backend, developers using Transformers can load the -hf checkpoints with standard Python. It lowers the setup cost without changing what the model recognizes.
The model cards list language identification and recognition across 30 languages — including English, Chinese, Korean, Japanese, Spanish, Arabic, Hindi, Thai, Vietnamese, and Polish — plus 22 Chinese dialects, for 52 languages and dialects total. Both sizes support streaming and offline inference from one model, accept long audio, and list singing and songs with background music as supported audio types.
Qwen3-ForcedAligner-0.6B adds forced alignment: given audio and a transcript, it marks each word's start and stop time to the millisecond across 11 languages, for clips up to five minutes. That enables clickable transcripts, subtitle timing, and jumps to the moment a word was spoken. Publishing an aligner alongside the recognizer makes the family useful for building transcription products, not just running a demo.
Qwen's model cards report results from the Hugging Face Open ASR Leaderboard dated June 26, 2026: mean word error rate is 5.59% for the 1.7B model and 6.31% for the 0.6B; on the AMI meeting-audio subset, the figures are 9.26% and 10.57%. Lower word error rate means fewer words are wrong. Qwen describes the 1.7B model as state of the art among open ASR models and competitive with commercial APIs; these are vendor-reported results. The independent board below uses different audio, so its scores are not directly comparable.
Whisper started this, and it is still the model everyone runs
None of this would exist in its current shape without OpenAI's Whisper. The repository went public on September 16, 2022, under the MIT license — code and weights both — at a moment when serious speech recognition meant a contract with a cloud vendor. It has since collected 106,679 GitHub stars.
What made Whisper matter was less the model than what the community built on it within months. whisper.cpp reimplemented it in plain C and C++, MIT-licensed, 52,591 stars, and made it run on laptops and phones with no Python and no GPU. faster-whisper rebuilt it on CTranslate2 for a large speed and memory win, MIT again, 24,750 stars. The model was the seed; the ecosystem was the tree.
Four years later, Whisper remains widely used. In the 30 days before August 5, 2026, whisper-large-v3-turbo was downloaded 8.72 million times from Hugging Face and whisper-large-v3 5.50 million; Qwen3-ASR-0.6B reached 4.29 million. On the Artificial Analysis board, Whisper Large v3 scores 4.07% AA-WER, compared with 1.73% for the leader in that snapshot.
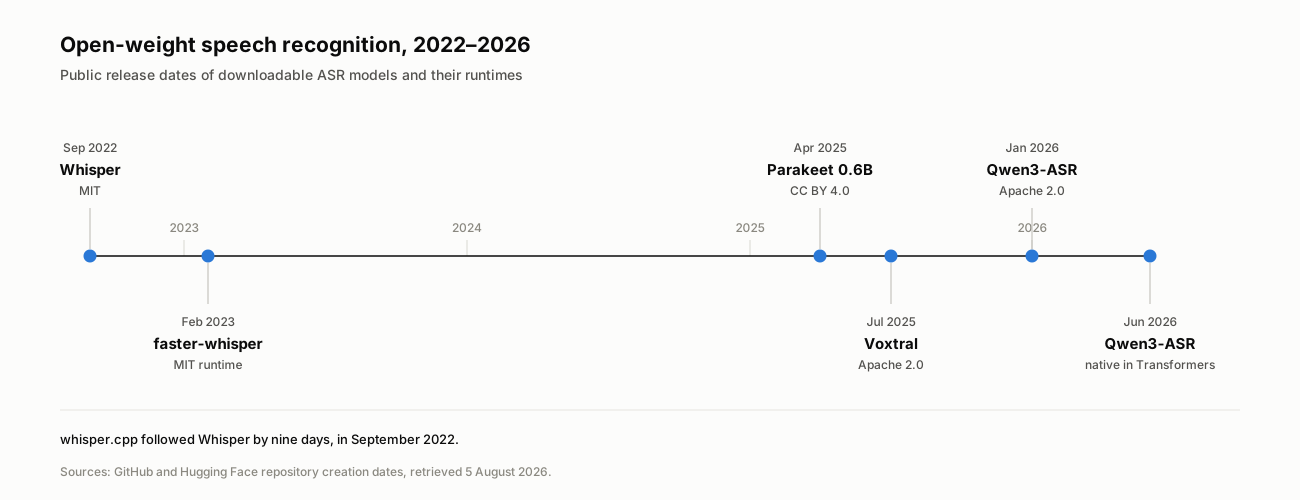
The open speech tier arrived in two bursts three years apart, with almost nothing in between. Release dates from GitHub and Hugging Face, retrieved August 5, 2026.
The open tier is wider than one lab
Qwen is not alone, and the others differ sharply in what they are good at.
NVIDIA's Parakeet line focuses on speed. parakeet-tdt-0.6b-v3, released in August 2025 under CC BY 4.0, has 600 million parameters, covers 25 European languages, and supports automatic language detection, punctuation, capitalization, and word-level timestamps for audio up to 24 minutes per pass. NVIDIA's Canary family — canary-1b-v2 and canary-qwen-2.5b, also CC BY 4.0 — offers related capabilities. Mistral's Voxtral models, released in July 2025 under Apache 2.0, rank near the top of the independent comparison below.
Here is the open tier side by side, with a hosted API on the last row for contrast.
| Model | Download | License | Languages | Runs on | Strongest at |
|---|---|---|---|---|---|
| Whisper Large v3 | 3.09 GB | MIT | 99 | Laptop or one GPU | Being the default everything already supports |
| Qwen3-ASR-0.6B | 1.56 GB | Apache 2.0 | 52 with dialects | Laptop | Multilingual work at the smallest size |
| Qwen3-ASR-1.7B | 4.08 GB | Apache 2.0 | 52 with dialects | Laptop or one GPU | Best accuracy in the Qwen family |
| Parakeet TDT 0.6B v3 | 2.51 GB | CC BY 4.0 | 25 European | Laptop or one GPU | Speed and word-level timestamps |
| Voxtral Small | — | Apache 2.0 | — | Server GPU, 24B parameters | Highest open score on the independent board |
| Hosted API | Not downloadable | Proprietary | Varies | The vendor's cloud | Diarization, streaming, uptime |
Download size is the default checkpoint in each Hugging Face repository. "—" indicates that the source material used for this comparison did not provide the value. Snapshot retrieved August 5, 2026.
Then there is the packaging work that gets these models onto actual devices, which is where the laptop tier stops being theoretical. whisperkit-coreml — Whisper compiled for Apple hardware — was downloaded 8.31 million times in the last 30 days. An MLX build of Parakeet for Apple Silicon took 1.87 million, and two GGUF conversions, the quantized format that runs models on ordinary CPUs, pulled 2.04 million and 1.87 million between them. Millions of people a month are downloading speech recognition packaged specifically to run on their own machine. That is not a research curiosity. That is a distribution channel.
The number one spot is still a preview endpoint you cannot download
The comparison separates recognition accuracy from the operational benefits of running a model yourself.
Artificial Analysis's speech-to-text board, retrieved August 5, 2026, measures open and closed models on the same audio. Its AA-WER v2 results include:
| Rank | Model | AA-WER | Downloadable? |
|---|---|---|---|
| 1 | Fun-Realtime-ASR-preview | 1.73% | No — preview endpoint |
| 2 | Scribe v2 (ElevenLabs) | 2.18% | No — hosted API |
| 3 | MAI-Transcribe-1.5 (Microsoft) | 2.38% | No — hosted API |
| 4 | Smallest AI Pulse Pro | 2.43% | No — hosted API |
| 5 | Voxtral Small (Mistral) | 2.77% | Yes — Apache 2.0 |
| 6 | Gemini 3.1 Pro Preview (High) | 2.82% | No — hosted API |
| 11 | Whisper Large v3 | 4.07% | Yes — MIT |
Source: Artificial Analysis speech-to-text leaderboard, AA-WER v2, retrieved August 5, 2026. Download status assessed from each model's published license.
The top four rows show that the best-scoring models in this snapshot are hosted, and the leader is a preview endpoint rather than a downloadable model.
Voxtral Small is Apache 2.0 and ranks fifth at 2.77%, roughly one percentage point behind the closed preview model at the top. For a 6,300-word hour-long meeting, that difference corresponds to about 66 words. It is a real gap, but not an insurmountable one for teams that value local deployment.
For many workloads, open speech models are already usable; the remaining decision is whether a modest accuracy gap is worth the control of self-hosting, or whether a hosted service's surrounding features justify its cost.
What running it yourself buys you, and what it costs
Three things push teams toward self-hosting, and none of them are accuracy.
Privacy is the first and usually the decisive one. If you transcribe medical consultations, legal interviews, or HR conversations, "the audio never leaves our hardware" is not a preference, it is a procurement requirement, and a model you host yourself is the only architecture that satisfies it cleanly. Offline operation is the second: a model on the device works on a plane, in a basement, on a factory floor, at a field site with no signal. That is exactly why whisper.cpp and the GGUF builds have the download numbers they do.
Cost is the third, and here the numbers are stark. From the same Artificial Analysis snapshot, price per 1,000 minutes of audio: Whisper Large v3 hosted on fal.ai runs $0.50, NVIDIA's Canary Qwen 2.5B on Replicate $0.74, Parakeet TDT 0.6B V3 on Together AI $1.50. On the closed side, Deepgram's Nova-3 is $4.30, MAI-Transcribe-1.5 is $6.00, and Gemini 3.1 Pro Preview runs $18.15. That is a 4x gap against Microsoft and a 12x gap against Google for hosting an open model on someone else's servers — before you consider running it on your own, where the marginal cost of the thousandth hour is electricity.
The speed figures in the same snapshot favor Parakeet TDT 0.6B V3 served on Together AI at 885x realtime — about four seconds to process an hour of audio. Deepgram's Nova-3 reaches 512x, Whisper Large v3 on Together 478x, and MAI-Transcribe-1.5 189x. The fastest listed option is an open-weight model, though this result measures Together AI hosting rather than local hardware.
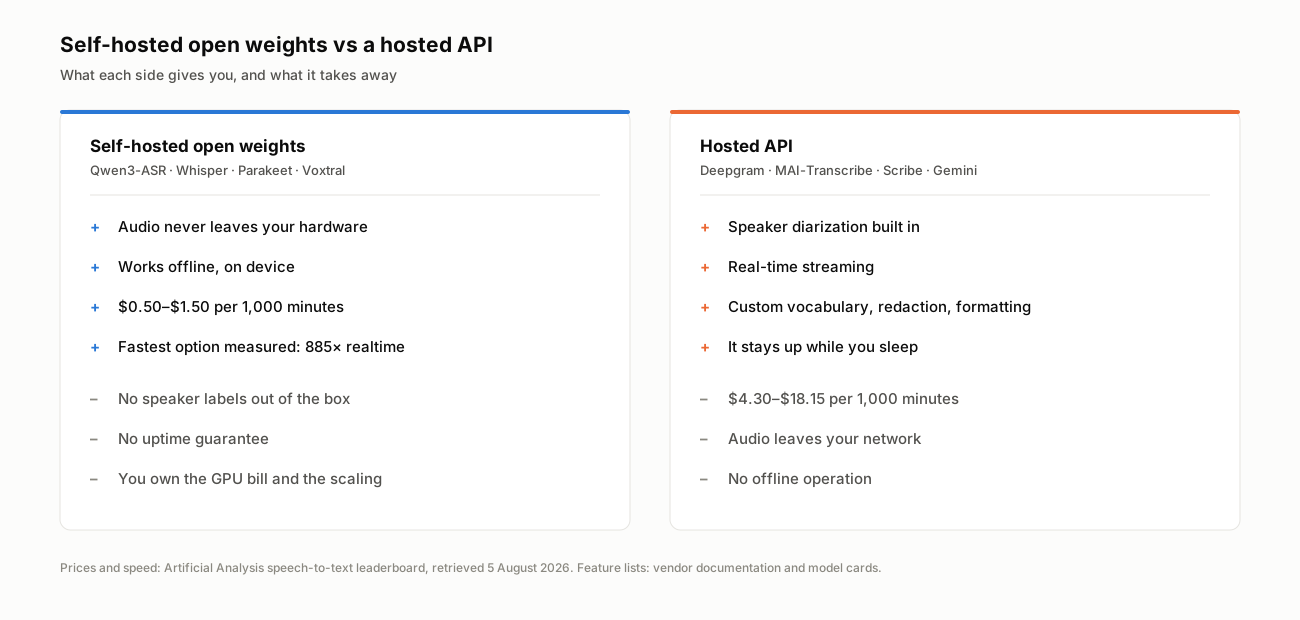
The trade was never accuracy against accuracy. It is control and cost against the features wrapped around recognition.
So what do the hosted APIs still sell? Everything that is not recognition. Deepgram's documentation is a fair inventory: speaker diarization, real-time streaming, formatting, custom vocabulary, entity redaction, language detection, and the guarantee that it stays up while you sleep. Download Qwen3-ASR and you get words and timestamps. No speaker labels, no SLA, and you own the GPU bill, the scaling, and the 3 a.m. page.
The most-downloaded model in the category is not a transcriber
Download patterns also show demand for speaker identification alongside transcription.
When you sort Hugging Face's entire automatic-speech-recognition category by downloads, the model at the top is not Whisper, not Qwen, not Parakeet. It is pyannote/speaker-diarization-3.1, with 8.91 million downloads in the last 30 days, and a second pyannote diarization model takes fifth place at 5.26 million. Diarization is the machinery that works out who spoke when — the layer directly above transcription.
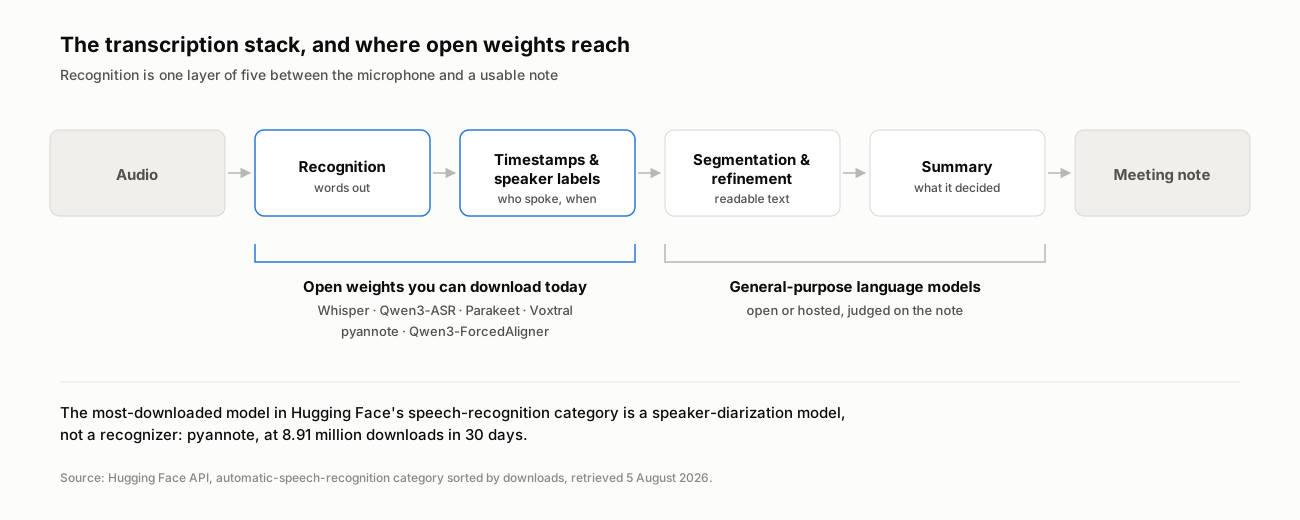
Open weights now cover the first two layers of the stack. The layers that decide whether a note is useful sit above them.
The most-downloaded model in the speech-recognition category does not recognize speech; it identifies who spoke when. That demand points to the layer above transcription, where speaker labels help turn recognized words into a useful meeting record. It echoes the product gap described in our analysis of the closed market.
The bottom line
The interesting question about open-weight speech recognition was never "is it as good as the closed models." It is within about a point of word error rate, it is faster, it is between four and twelve times cheaper, and it fits on a laptop. The interesting question is what you build in the space that opens up when transcription stops being a line item you rent — because a 1.56 GB file that hears 52 languages is not a product. It is a component that just became free.
For a team choosing a meeting-notes tool rather than a model, the practical read is short. Whether a product runs an open model or a closed API is now largely an implementation detail, and increasingly it will be both — open weights for the bulk work, hosted APIs where diarization and streaming and scale earn their price. Telli.sh already runs an open model in its summarization layer, so improvements in the open tier flow straight through to transcription, translation, and meeting notes without a price change. Judge the tool by what comes out at the end: whether the note tells you who committed to what.
Sources
- Qwen3-ASR-0.6B-hf model card (Hugging Face) — license, language list, leaderboard figures dated June 26, 2026
- Qwen3-ASR-1.7B-hf model card (Hugging Face)
- Qwen3-ForcedAligner-0.6B (Hugging Face)
- Qwen3-ASR Technical Report, arXiv:2601.21337 (submitted January 29, 2026)
- OpenAI Whisper repository (MIT, published September 16, 2022)
- whisper.cpp and faster-whisper
- NVIDIA parakeet-tdt-0.6b-v3 model card (CC BY 4.0)
- Mistral Voxtral-Small-24B-2507 (Apache 2.0)
- Artificial Analysis speech-to-text leaderboard — AA-WER v2, speed and price figures retrieved August 5, 2026
- Hugging Face Open ASR Leaderboard
- Deepgram speaker diarization documentation
- Wikimedia Commons image page
