Google advances live translation. OpenAI opens full-duplex voice. What comes next?
GPT-Live-1 reaches the API at $0.05 a voice minute, three months after Google's 70-language live speech translation. What the published prices and benchmarks measure, what they don't, and why meeting records, shared ideas, and saved sources matter more as conversation gets easier.
An original conceptual illustration. More natural conversation and a useful record of that conversation are complementary design goals, not measured stages of a product release.
The most encouraging thing about the latest voice AI announcements is an ordinary possibility: being able to finish a thought in your own language, clarify it halfway through, and still feel part of the conversation. Less waiting for a translation. Less rehearsing a sentence before you dare to join in. More attention available for what another person actually means.
Google introduced Gemini 3.5 Live Translate on June 9, 2026. OpenAI introduced its full-duplex GPT-Live models in ChatGPT on July 8, then released GPT-Live-1 in the API on September 10. These are different products serving different purposes, but the sequence points toward more continuous spoken interaction. The latest OpenAI announcement extends access for developers; it is not the first appearance of GPT-Live. Google's June announcement, OpenAI's July introduction, OpenAI's September API release.
My view is that this brings a world with fewer everyday language barriers closer. It also sharpens a second question: after a conversation becomes easier to have, how do we preserve what made it worth having? Meeting notes, shared ideas, and saved source material become part of the answer.
Full-duplex voice changes who has to wait
Full-duplex means a system can listen and speak at the same time. OpenAI describes GPT-Live-1 this way in its current model documentation, alongside the ability to delegate reasoning and tool use to a backend agent. That is a statement about simultaneous interaction, not a certificate of perfect translation. GPT-Live-1 model documentation, checked September 11, 2026.
Imagine correcting an assistant while it explains a plan: “Actually, the customer is in Madrid, not Mexico City.” A useful spoken interface needs to notice that correction before carrying on with the wrong assumption. It also needs to distinguish a correction from a brief acknowledgment, or a pause to think from an invitation to take over. The quality of the exchange depends on those small judgments.
Older voice interfaces often made their turn structure conspicuous. You spoke, waited for processing, listened, and then tried again. Faster processing helps, but an interaction can still feel awkward when the system guesses that you are finished too early. Full-duplex design addresses the overlap itself, rather than treating every moment of speech as a neatly closed message.
In early evaluations reported by OpenAI, language-learning company Speak saw almost 80% fewer interruptions during learners' thinking pauses than with previous turn-based systems. This partner result concerns interruption behavior, not translation accuracy, and may not generalize to every language or setting. OpenAI's API launch report, September 10, 2026.
OpenAI reports that GPT-Live-1 scores 30 percentage points higher than GPT-Realtime-2.1 on Full Duplex Bench, which tests pauses, turn-taking, interruptions, and backchannels. Paired with GPT-6 Astra at medium reasoning effort, it ranks first on Tau3 for spoken customer-service and banking tasks, including 97 banking-knowledge tasks. These vendor evaluations measure conversational behavior and task completion, not translation accuracy. OpenAI's evaluation summary, September 10, 2026.
For someone speaking a second language, a thinking pause may be exactly where participation becomes difficult. An assistant that waits appropriately leaves room to find a word. An assistant that accepts a correction makes it less costly to try. Those are practical reasons to be excited about natural voice interaction beyond how impressive a demonstration sounds.
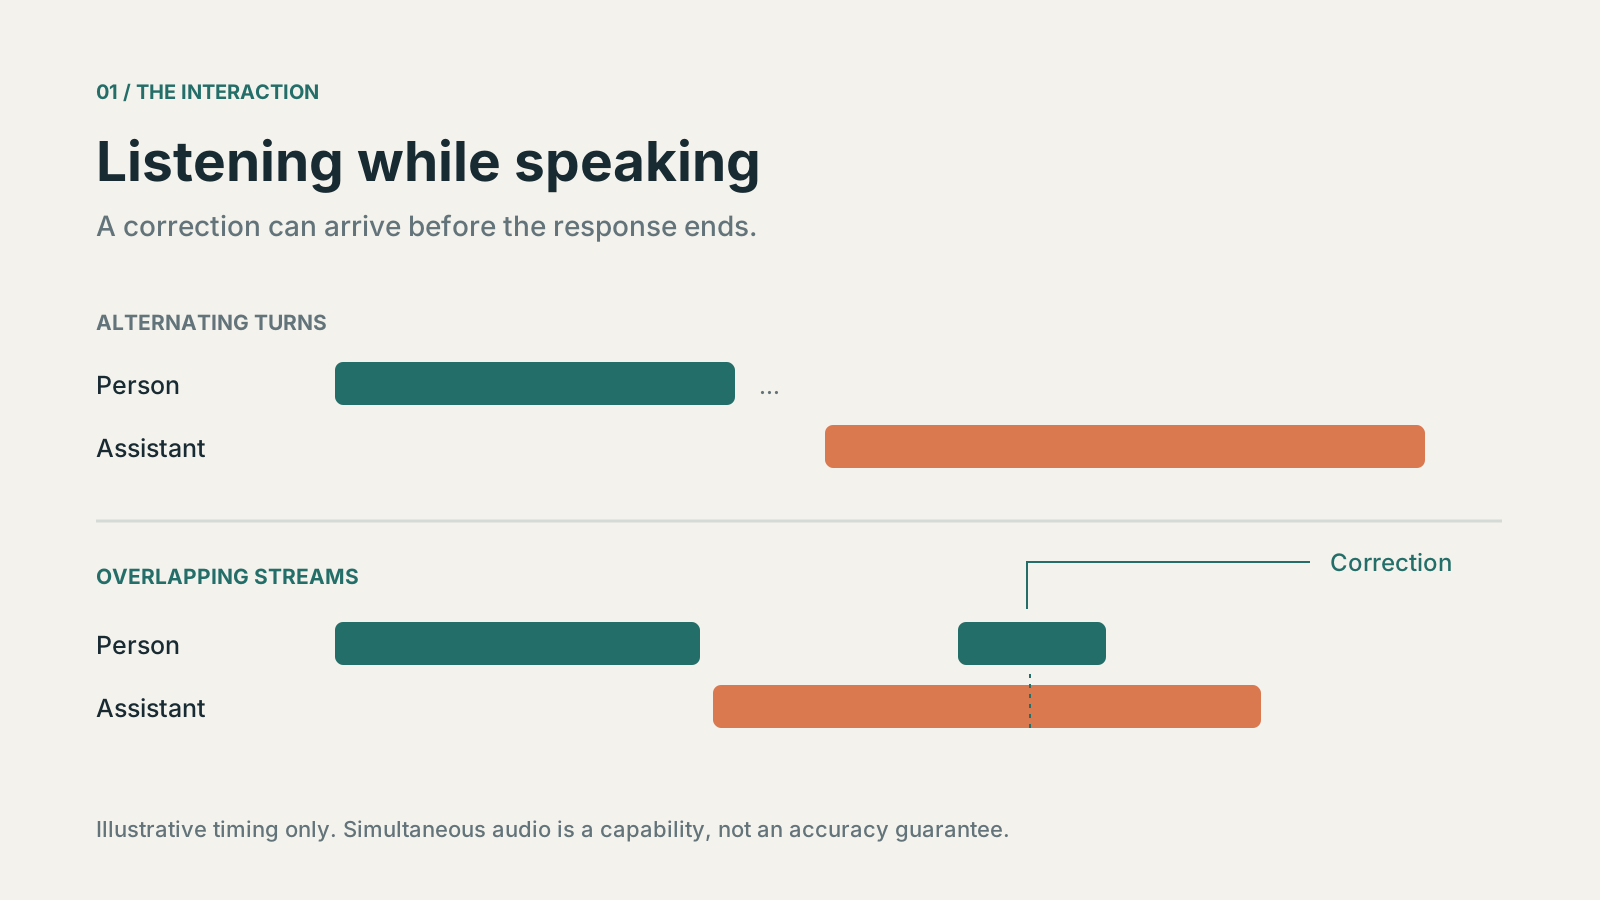
Conceptual timing only; the bars do not represent measured latency. Full-duplex describes simultaneous input and output, while useful interruption handling still depends on the model and application.
Live translation and a talking assistant have different jobs
Google's June announcement describes continuous speech translation across more than 70 languages. The model generates translated speech while listening, balancing the need for more context against staying close to the speaker. Google says it remains a few seconds behind, which is a more useful expectation than imagining zero delay. The developer release was a public preview. Google's launch description, June 9, 2026.
The scale figures in that announcement are specific. Speech translation in Google Meet is moving from five supported languages to more than 70, and from translating only to and from English to more than 2,000 language combinations in one meeting. It starts as a private preview for selected business Workspace customers, with a broader rollout later in 2026. Grab is testing the model for pickups between drivers and travelers, a use case with more than 10 million voice calls a month. The announcement cites partner praise for quality, accuracy, and low latency but does not give a numeric score for those measures. Google's launch figures, June 9, 2026.
There is a distinction worth keeping visible. Google's Live Translation guide describes an interpreter that processes an audio stream continuously, with translation-specific settings and no support for tools or general instructions. GPT-Live-1 is a conversational model that can work with a separate agent. One helps carry a speaker's meaning into another language; the other participates in the exchange. They should not be presented as interchangeable services. Google's Live Translation guide, OpenAI's model documentation, checked September 11, 2026.
| Milestone | What was announced | Availability or scope |
|---|---|---|
| Google, June 9, 2026 | Gemini 3.5 Live Translate; continuous speech translation | Developer public preview at announcement; language-pair quality can vary |
| OpenAI, July 8, 2026 | GPT-Live rollout in ChatGPT, with simultaneous listening and speaking | Conversational voice is not the same as interpreter-level translation |
| OpenAI, September 10, 2026 | GPT-Live-1 API access for building voice applications | Developers still need to integrate it into their own products |
Release timing and scope are from the linked announcements; the products serve different jobs and are not ranked against each other.
Taken together, these developments make a compelling direction visible: translation can become more continuous, and interaction with an assistant can become less rigid. Connecting those capabilities into a reliable multilingual meeting experience remains application work. Someone still has to decide whose audio is being interpreted, where the result goes, how corrections are handled, and what the participants see.
The published numbers: $0.05 a minute, and no accuracy score
A minute of GPT-Live-1 voice costs $0.05 in the API, billed per second without rounding up to a whole minute. That price covers the front-end voice layer only; the backend model and tools a session delegates to are billed separately at their normal rates. OpenAI's model documentation, checked September 11, 2026.
At that rate, 30 minutes costs $1.50 in voice-layer time, an hour costs $3.00, and 100 hours a month comes to $300 before backend reasoning. An application that gives each participant a separate session multiplies the total by the number of sessions. Google's June announcement did not list a price for Gemini 3.5 Live Translate, so these figures are not a cost comparison.
| Figure | Value | Source and date | What it measures |
|---|---|---|---|
| GPT-Live-1 API price | $0.05 per minute, billed per second | OpenAI, Sept 10, 2026 | Voice layer only; backend model and tools billed separately |
| Full Duplex Bench | +30 percentage points vs GPT-Realtime-2.1 | OpenAI, Sept 10, 2026 | Pauses, turn-taking and interruptions, not translation |
| Tau3 | Ranked first, with GPT-6 Astra (medium) | OpenAI, Sept 10, 2026 | Spoken task success (Pass@1), including 97 banking tasks |
| Speak early evaluation | Almost 80% fewer interruptions in thinking pauses | OpenAI (partner quote), Sept 10, 2026 | Interruption behavior versus earlier turn-based systems |
| ChatGPT voice use | More than 150 million people a week | OpenAI, July 8, 2026 | Voice and Dictation usage, not quality |
| Gemini 3.5 Live Translate | 70+ languages, detected automatically | Google, June 9, 2026 | Coverage, not per-pair quality |
| Google Meet speech translation | 5 → 70+ languages; 2,000+ combinations per meeting | Google, June 9, 2026 | Planned upgrade, private preview first |
| Translation delay | "Just a few seconds behind the speaker" | Google, June 9, 2026 | Vendor description, not a measured figure |
Every figure is vendor-reported and comes from the announcements and documentation linked in this post. None of them is a numeric translation-accuracy score, such as a human rating or an automatic metric for a language pair.
That gap matters most for anyone choosing a tool for multilingual meetings. Interaction benchmarks tell you whether a system waits, listens and recovers well; they do not tell you whether "Monday" survived the trip into Korean. OpenAI's July caveat about non-native accents in some languages and the absence of per-pair scores from Google point to the same practical rule: test the language pairs your team actually uses before relying on either for decisions.
A lower language barrier starts with being willing to speak
Consider a hypothetical 30-minute project meeting with four people who are most comfortable in three different languages. The benefit of better spoken translation is not merely that each person hears more words. It is that the group can ask follow-up questions before an uncertainty becomes a misunderstanding. A tentative idea can be expressed without first being polished into a second language.
That changes the economics of participation in a very ordinary sense: contributing takes less effort. The quiet person with relevant experience has another way into the discussion. The person leading the meeting can spend less time reconstructing an interrupted sentence. A clarification can happen when it is useful, while everyone still remembers the point being discussed.
Remote teams, classroom discussions, customer conversations, and informal exchanges while traveling are all settings where continuous translation could reduce the effort of joining in. The result still depends on language pair, accent, vocabulary, microphone quality, and the product delivering the translation.
OpenAI's July introduction noted non-native accent or fluency gaps in some languages. Teams should evaluate the language pairs and accents they actually use instead of assuming a smooth English demonstration predicts their results. OpenAI's GPT-Live introduction, July 8, 2026.
The right ambition is broader participation with an easy way to clarify. A date, an amount, a person's name, or a conditional promise should remain easy to check. A system can sound confident while a participant still needs to say, “Please show me that sentence.” Showing the text and retaining the original, where participants have agreed to recording, gives that request somewhere to go.
A fluent meeting still needs a record of its decisions
Return to the hypothetical project meeting. Someone says, “We could ship on Friday if the security review is finished.” Another person says that Monday would give support more preparation time. The group eventually chooses Monday, assigns an owner, and leaves one dependency unresolved. A summary that remembers only the first proposed date has missed the meeting's outcome.
No improvement in conversational rhythm removes the difference between a suggestion, a condition, and a decision. People working in the same language already need to distinguish them. Multilingual interaction makes it more valuable to preserve the path from the original statement to the translated wording and the final agreed action.
For a practical meeting record, I would want a reader who missed the call to find three things quickly: what the group decided, who is responsible for the next step, and which questions remain open. A deadline should be described as agreed only when it was agreed. If the source is unclear, the record should carry that uncertainty forward instead of tidying it into a false conclusion.
This does not require turning every conversation into an exhaustive archive. A short decision note can be more useful than pages of undifferentiated transcript. The important relationship is between the concise account and the supporting material: the relevant original wording, the recording when available and authorized, and the document the group was discussing.
That relationship is also what makes correction affordable. A participant can point to the source, adjust a mistaken summary, and share the corrected decision. Without it, the next person may summarize an earlier summary and turn an initial misunderstanding into an apparently settled fact. Better speech makes the live exchange easier; good records make the result easier to trust later.
Shared ideas need the source that gave them meaning
A useful idea rarely begins and ends inside one call. Someone finds an article, saves a passage, asks a question about it, and brings the question to a meeting. Another person adds a counterexample from a video or a research paper. The next step depends on being able to reconnect those pieces after the conversation has ended.
This is why clipping web material still matters in a world of excellent voice AI. A saved URL lets someone return to the source. A selected passage identifies the part that mattered. A short personal note explains why it was saved. These are different contributions, and keeping them together makes sharing an idea more useful than forwarding an isolated AI-generated paragraph.
For example, “We should change onboarding” is a weak handoff. “This article raised a question about the first five minutes; here is the passage, our discussion, and the experiment we agreed to try” gives the next reader something to examine. The example is illustrative, but the distinction is concrete: sharing the conclusion alone asks for trust; sharing the reasoning and source supports a conversation.
The same discipline protects the source from being blurred into commentary. A quotation should remain identifiable as a quotation. A translation is an interpretation of that source, and a meeting summary is another derived view. Keeping those roles visible lets people disagree productively without first having to reconstruct what anyone originally said.
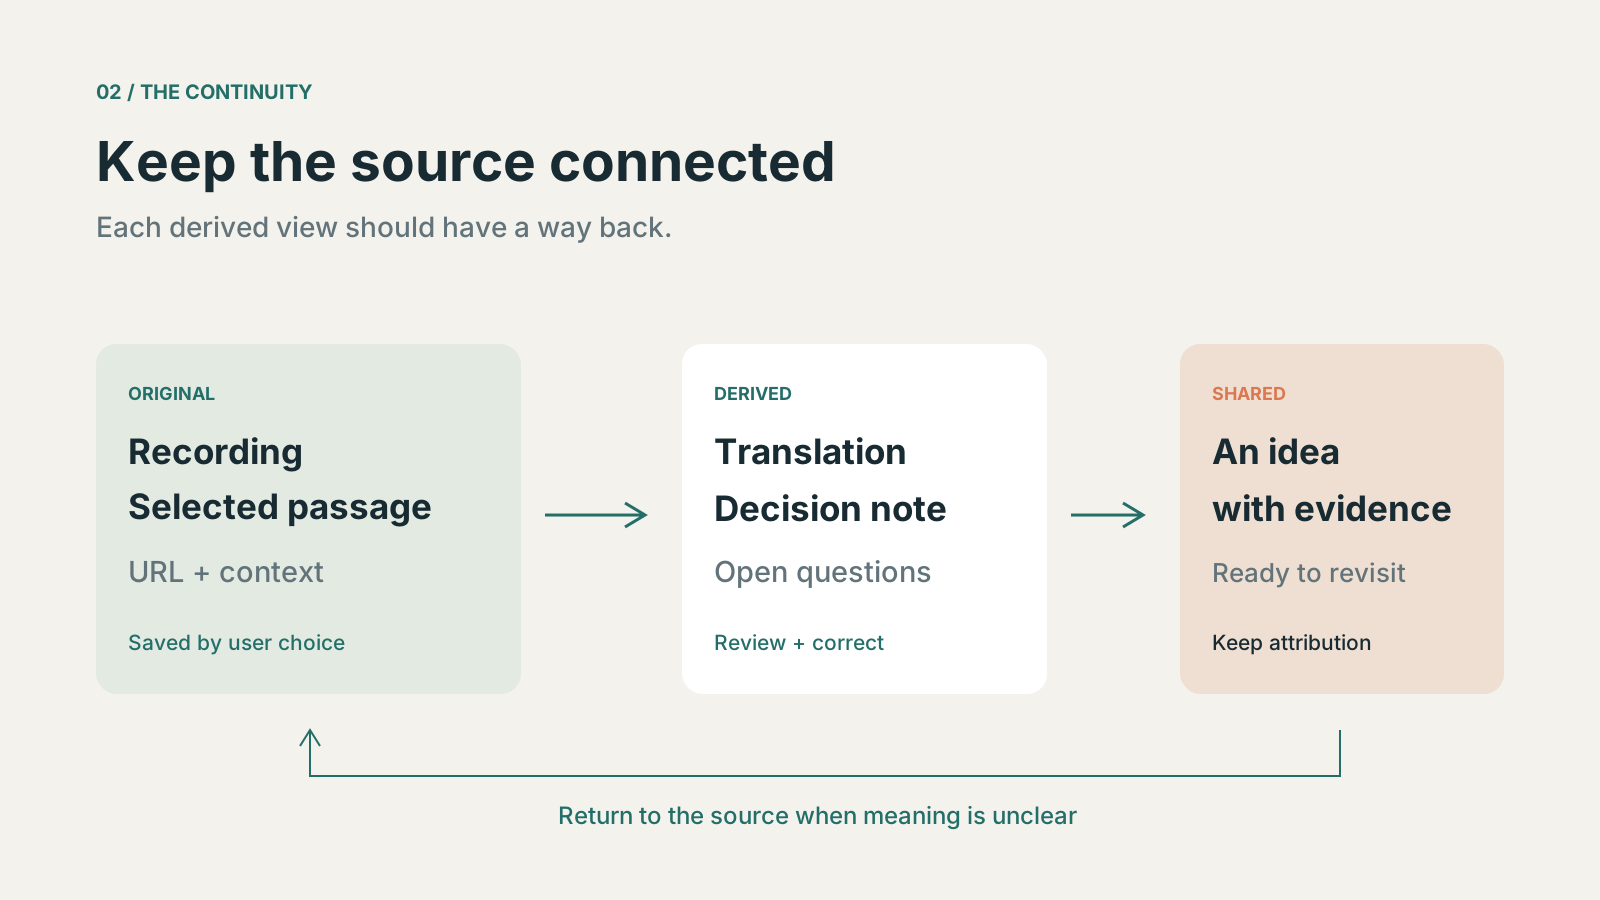
An original proposed workflow. Preserve authorized source material, make derived text correctable, and keep the connection visible when sharing. The diagram does not claim that every link is an automated feature today.
The lasting challenge is continuity after the call
Voice systems are also starting to separate the conversation from work happening behind it. OpenAI's delegation documentation explains that live speech and delegated work can continue independently; a completed backend response does not establish that the user heard the answer. This is a useful engineering reminder of a broader product problem: a spoken experience and a durable outcome are separate things to verify. OpenAI's delegation documentation, checked September 11, 2026.
For everyday users, the question is simpler. When a call ends, can I find the decision tomorrow? Can a colleague understand why we made it? Can I return to the article that challenged our assumption, without searching across a chat history, a browser, and a recording? Those questions remain even if every sentence is interpreted beautifully.
There is reason to be optimistic about language barriers becoming less dominant. We should welcome tools that let more people contribute comfortably. My expectation is that easier conversation will increase the value of connecting what we say to what we keep, share, and eventually do. The meeting does not have to live forever; its useful outcome should survive the call.
Where we want to take Telli.sh
For Telli.sh, this is a direction worth building toward: help people turn conversations and discoveries into knowledge they can return to. Today, the product brings notes, recordings, translations, and Clips into a shared workspace. The next steps should strengthen the connections among those materials, so a meeting record, an idea, and its source do not become separate fragments again.
We want the workflow to feel continuous: capture an authorized conversation, review its important points, keep the decisions understandable, and share an idea together with the material that supports it. When a web page starts the discussion, Clip should help preserve the URL and the context the user chooses to save. When a translation helps someone understand, the original should remain available for correction and comparison.
Telli.sh has not integrated GPT-Live-1 or Gemini 3.5 Live Translate. Any future voice integration should earn its place through useful results across languages, dependable records, and clear control over what is saved. The goal is to make the workspace more useful as underlying models improve, without making a person's knowledge depend on a single model.
As speaking across languages becomes easier, we want to help the value of those conversations last longer. Start with one meeting worth remembering, one idea worth sharing, or one source you know you will need again.