120 free minutes that cannot hold one interview: what free AI transcription really gives you in Bahasa Indonesia
Compare free AI transcription limits for Bahasa Indonesia: Notta's recording cap, TurboScribe's daily files, Google's API option, and Deepgram's batch-model update. A practical guide to choosing a workflow for an interview.
You have a 47-minute interview sitting on your phone. A source in Surabaya, recorded this morning, mostly Bahasa Indonesia with the usual scatter of English — deadline, stakeholder, follow up. You need a transcript today, and you would strongly prefer not to pay for one.
So you search, you land on a tool advertising 120 free transcription minutes a month, and you sign up. Your 47-minute file is well inside 120. Then the upload fails, and buried in the plan comparison is a second number nobody puts in the headline: maximum transcription per recording, 3 minutes.
That is the shape of this whole category. Free tiers are advertised on the number that sounds most generous and constrained by a different number three rows down. This post is the comparison we wish existed: what each free tier actually gives an Indonesian-language interview, what it silently refuses, and how to test any of them in five minutes before you commit.
TL;DR
- Free tiers have three independent ceilings — minutes per month, minutes per file, and files per day — and the one that breaks interviews is almost always the per-file cap, not the monthly total.
- Indonesian speech recognition genuinely improved this month: Deepgram shipped an upgraded Nova-3 Indonesian model on August 7, 2026, but on the batch path only, not streaming. Uploading a recording benefits; live captioning does not.
- A public leaderboard cannot substitute for testing your actual interview. Use a 5-minute Indonesian clip with the accents, recording conditions, and code-switching you expect; corpus scores provide context, not a guarantee for those speakers.
The free tiers, side by side
Every figure below comes from the vendor's own published pricing or documentation, retrieved on August 31, 2026. The reference job is one 47-minute two-person interview, because that is the file people actually have.
| Tool | Free tier | Longest single file, free | Indonesian | Paid entry point |
|---|---|---|---|---|
| Notta | 120 min/month, 50 uploads/month, 10 AI summaries/month, 1 seat | 3 minutes | Yes (official language list) | Pro $8.17/month billed annually — 1,800 min/month, 5-hour files |
| TurboScribe | 3 transcripts per day, lower queue priority | 30 minutes | Yes | Unlimited $10/month, $120 billed yearly — 10-hour files |
| Transkriptor | No free monthly minutes published | — | Yes | Lite $9.99/month — 300 min/month |
| Maestra | No free monthly minutes published | — | Yes | Pay-as-you-go $12 per 60 minutes; Lite $23/month — 180 min/month |
| Google Cloud Speech-to-Text | 60 min/month, then $0.016/min | No practical cap | Yes, id-ID | $0.016/min with data logging, $0.024/min without |
| OpenAI transcription API | None | No practical cap | Yes | $0.006/min (gpt-4o-transcribe), $0.003/min (mini) |
| Whisper, self-hosted | Unlimited, MIT-licensed | Your hardware | Yes | Free software, your own GPU time |
| Telli.sh | 60 min/month | Up to the allowance | Yes | Paid plans start at 300 min/month |
Sources: each vendor's pricing page, retrieved August 31, 2026; Google's supported-languages documentation for id-ID; OpenAI's published API pricing; and Notta's supported-language list, which includes Indonesian for monolingual transcription and translation after transcription. TurboScribe figures use an Internet Archive pricing-page snapshot; current plans may differ.
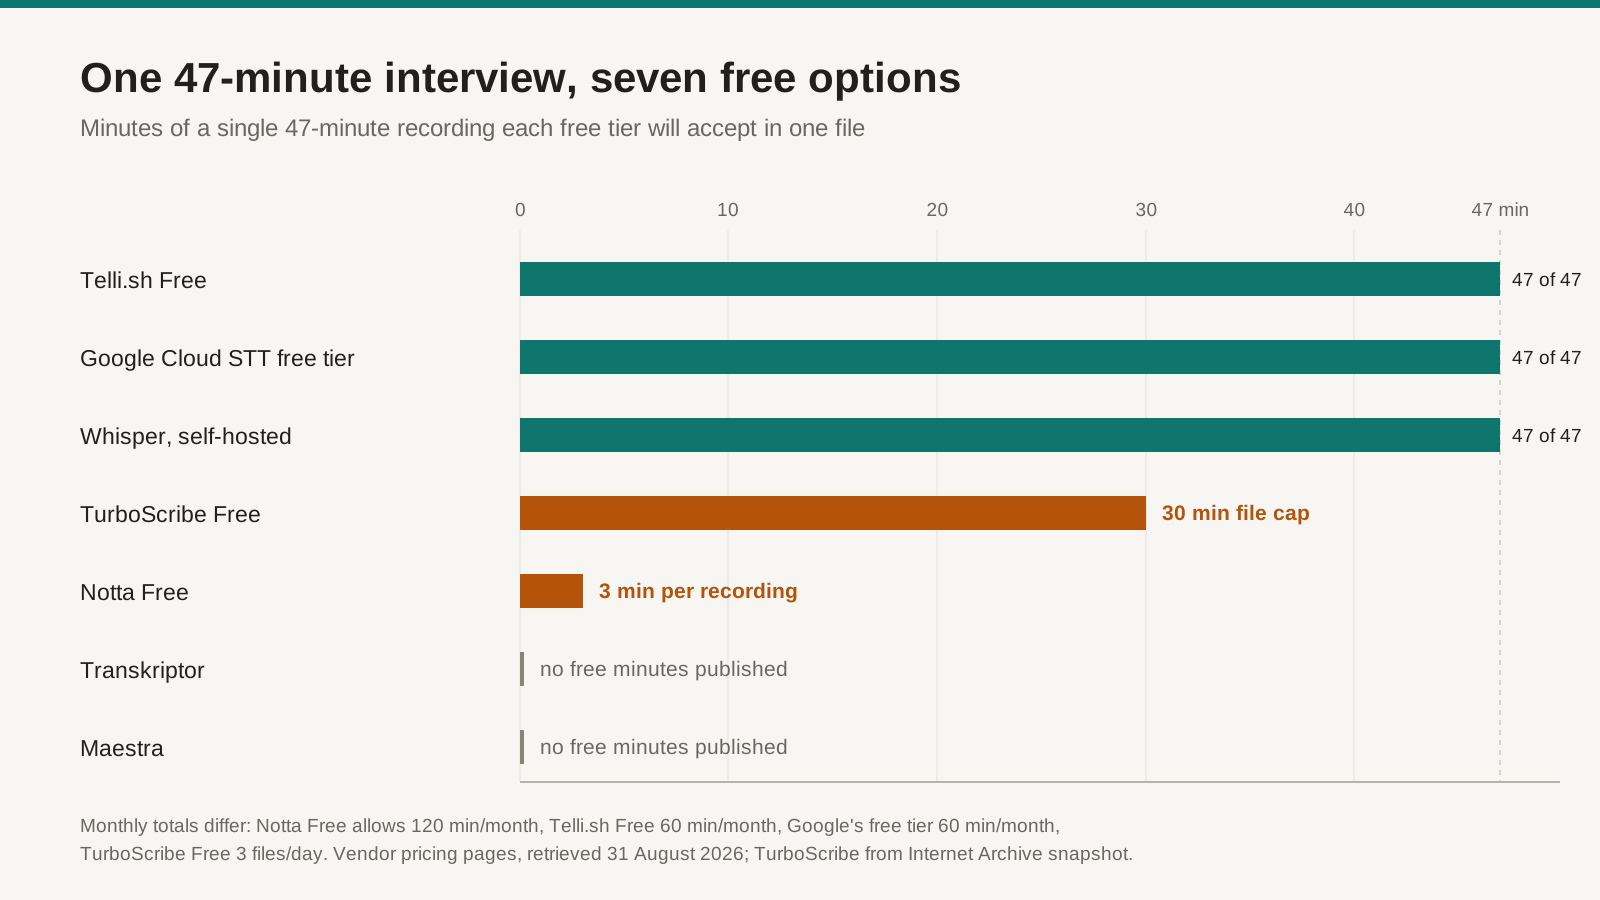
Same unit on one axis: minutes of one 47-minute interview accepted in a single file. Monthly allowances differ and are noted below the chart.
Notta's 120 minutes are real. The three-minute ceiling is what breaks the interview.
Read the Notta free plan carefully and it is not stingy — 120 transcription minutes a month, 50 file uploads, 10 AI summaries, 1,000 AI credits, no credit card. For voice memos and short calls that is a genuinely useful allowance, and it is more monthly minutes than most competitors give away.
Then read one row further down the same comparison table: max transcription per recording, 3 minutes on Free, against 5 hours on Pro. Your 120 minutes are 40 separate three-minute fragments. A 47-minute interview cannot enter the system at all.
Here's the point, and it generalizes past any one vendor: a free tier is not one number, it is three ceilings, and the marketing quotes whichever is highest. Minutes per month is the headline. Minutes per file is the one that decides whether your interview is transcribable. Files per day is the one that decides whether you can process a week of fieldwork on a Sunday.
TurboScribe inverts the same trade. Its free plan advertises no monthly minute pool at all — three transcripts a day, each up to 30 minutes, one file at a time, at lower queue priority. Three 30-minute files a day is 90 minutes of audio, well past Notta's monthly 120 within two days. But a 47-minute interview still does not fit, because the binding constraint is again the per-file cap. You would have to split the recording, and every split costs you the speaker continuity across the cut.
Transkriptor and Maestra resolve the tension differently: they mostly do not have a free tier. Transkriptor's published plans start at Lite, $9.99 a month for 300 transcription minutes, rising to Pro at $19.99 for 2,400 minutes ($8.33 a month if you pay $99.99 for the year). Maestra sells pay-as-you-go credits at $12 per 60 minutes, with Lite at $23 a month for 180 minutes. Both list Indonesian; Maestra's language table marks Indonesian as supported for transcription, translation, voiceover, and real-time alike. Neither publishes a recurring free allowance, which is its own kind of honesty.
Indonesian got measurably better on August 7 — on exactly one path
Something real happened to Indonesian speech recognition this month, and almost nobody covering "AI transcription tools" mentioned it.
On August 7, 2026, Deepgram released improved Nova-3 monolingual models and added Armenian. The changelog is specific in a way vendor announcements rarely are. Under Batch models: Tamil and Indonesian. Under Streaming models: Tamil and Belarusian.
Indonesian appears in one list and not the other.
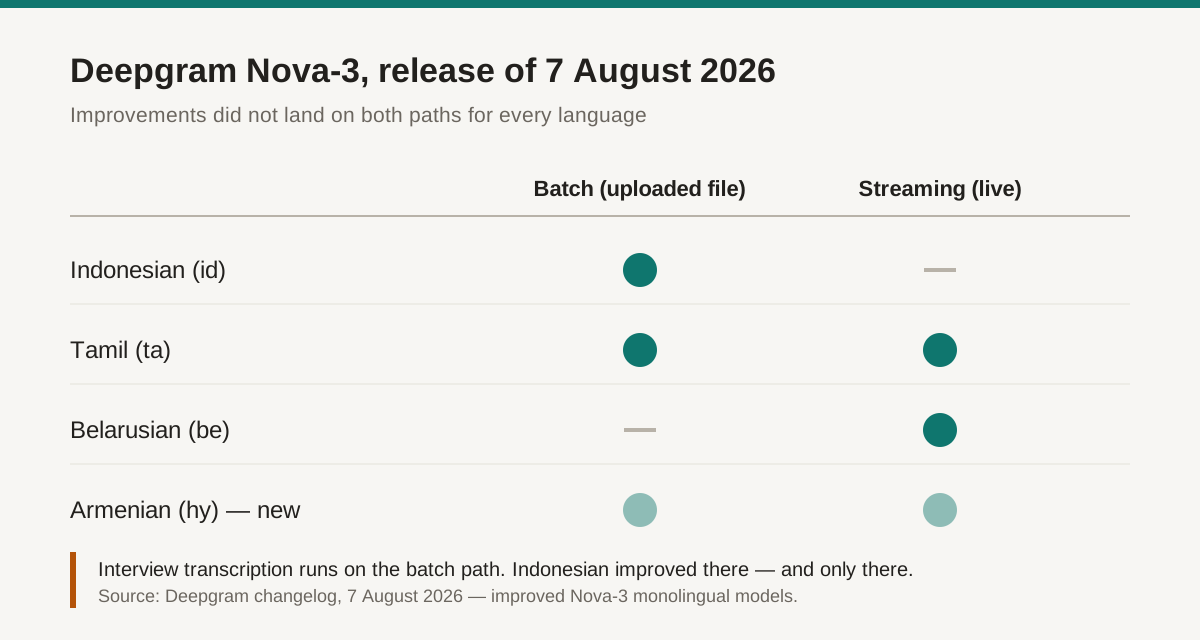
The same release improved Indonesian in batch and Belarusian in streaming. "Improved Indonesian support" is not one fact. Source: Deepgram changelog, August 7, 2026.
That distinction lands directly on interview work. Batch is the path an uploaded file takes — the engine sees the whole recording, can use context from both directions, and is not racing a live audio buffer. Streaming is the path live captions take. If you record an interview and upload it afterward, you are on the batch path, which is the path Indonesian improved on this month. If you were hoping for accurate live Indonesian captions during the interview itself, that specific model did not change on August 7.
We wrote the longer version of this argument in what "supported" actually hides in speech-to-text language coverage, because the pattern repeats across the industry: a language is not supported or unsupported, it is supported on a path, in a mode, at a quality tier, as of a date. For interview transcription specifically, the good news is that the path you need is the one that got better.
Nobody publishes an Indonesian accuracy benchmark, so you have to be the benchmark
A reliable public WER benchmark for Indonesian is hard to find, so published rankings cannot tell you how a tool will handle your audio.
The Open ASR Leaderboard — the closest thing the field has to a neutral scoreboard — ran a multilingual tab covering only European languages until August 28, 2026, when Hugging Face and Voice Arena added Hindi as its first Global South language. Indonesian, with roughly 280 million people in its home market, is still not on it. Vendors publish accuracy claims for English and stay quiet elsewhere.
Whisper's own structure hints at the same asymmetry. OpenAI's tokenizer declares 100 language tokens, and Indonesian sits at position 17 in that table — respectable, comfortably ahead of most of the list, and nowhere near the data volume behind English, Chinese, or Spanish. A declared token is not a quality guarantee; it is a statement that the model will attempt the language.
So the honest operational conclusion is this: for Indonesian, the benchmark is your own audio. Not the vendor's demo file, not a leaderboard, not a review site's star rating. Your recorder, your room, your interviewee's regional accent, your industry's vocabulary. That sounds like a cop-out until you notice it takes about twenty minutes to do properly.
The 5-minute test: run this before you pay anyone
Take one five-minute slice of a real interview — ideally one with two speakers, background noise, and at least three proper nouns. Run it through every candidate. Then check five things, in this order.
- Count the proper-noun errors. Names of people, companies, places, and product terms. These are where Indonesian ASR reliably fails and where an error does the most downstream damage, because a wrong name propagates silently into every summary and quote you generate afterward. Five errors in five minutes is roughly 47 in your interview.
- Check the mixed-language lines specifically. Find a sentence where an English word sits inside an Indonesian clause and read what the tool produced. This is the single most predictive test for professional Indonesian audio, and it is the one no vendor page addresses.
- Verify the speaker labels at minute five, not minute one. Diarization usually looks perfect in the opening seconds. What matters is whether Speaker A is still Speaker A after the first interruption, cross-talk, or long pause.
- Look for timestamps you can act on. If you will ever need to verify a quote against the audio, you need line-level timestamps in the export, not just in the web player. Journalists and qualitative researchers should treat this as mandatory.
- Export the file and open it somewhere else. TXT, DOCX, SRT, VTT — whatever your workflow needs. This is where free tiers most often stop, and a transcript you cannot get out of the tool is a demo, not a record.
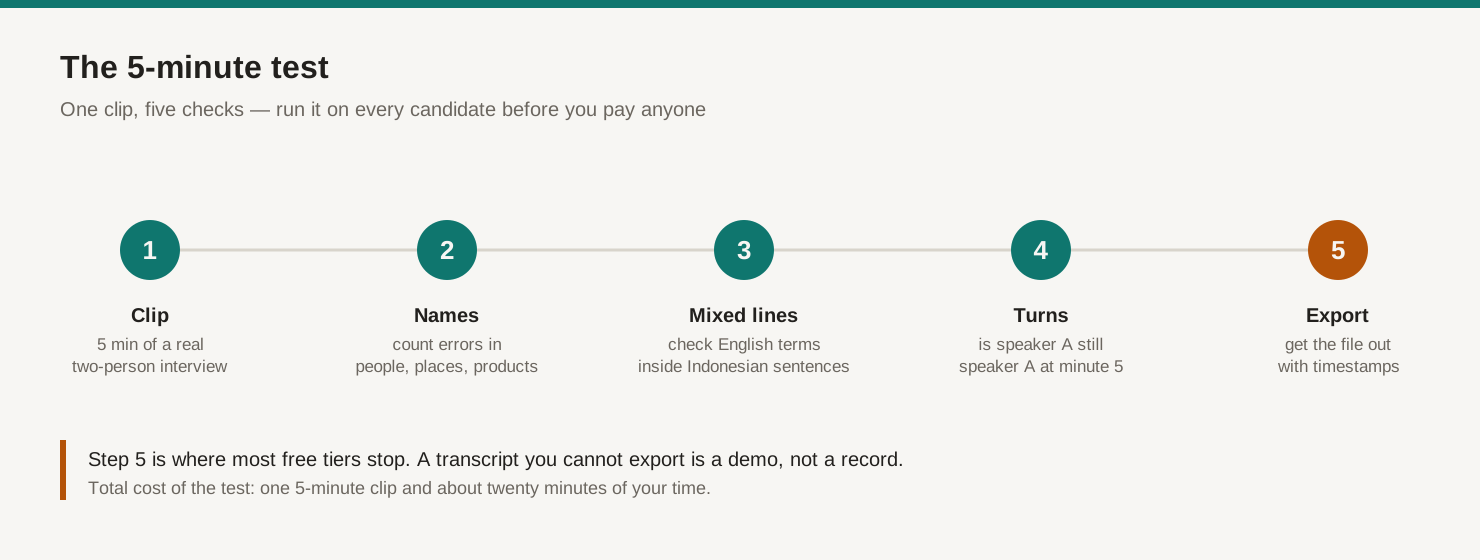
The five checks, in the order a real evaluation hits them.
If you want the workflow that comes after the tool choice — reviewing the transcript before you trust the summary, keeping quotes tied to source audio — we covered that separately in turning interview audio into a reviewable transcript and summary.
Where Indonesian interviews actually break: the English word in the middle of the sentence
Professional Indonesian is not monolingual. "Nanti kita follow up setelah meeting dengan tim product" is not broken Indonesian; it is how a product manager in Jakarta talks, and roughly how a recruiter, consultant, and startup founder talk too. Any transcript that mangles the English fragments has mangled exactly the terms your notes depend on.
This is the hardest thing in the category, and it is worth understanding why. Most speech engines run one monolingual model per request. You set the language to Indonesian, and the model is strongest on Indonesian phonetics and an Indonesian vocabulary — which means an English word arriving mid-sentence is either transliterated into something Indonesian-shaped or dropped. Setting the language to English inverts the damage. Multi-language or code-switching modes exist, but they are narrower than the monolingual lists: as of August 2026, Deepgram's Nova-3 documents 58 languages one at a time and code-switching in exactly 10.
Two practical mitigations, both cheap. First, set the source language explicitly to Indonesian rather than leaving auto-detect on — auto-detection commits to a guess from the least contextual seconds of the whole file, and a wrong guess degrades everything downstream at once. Second, if the tool offers a custom vocabulary or keyword list, put your recurring English terms and proper nouns in it before the run, not after.
Call this the gado-gado problem: the audio is mixed by design, and every engine wants to serve it as one dish.
If you can write code, transcription costs less than a cup of coffee
The free-tier comparison changes shape entirely if you are willing to touch an API, and the numbers are worth knowing even if you decide not to.
OpenAI charges $0.006 per minute for gpt-4o-transcribe and $0.003 per minute for the mini variant. Your 47-minute interview costs 28 cents, or 14 cents on mini. Google Cloud Speech-to-Text gives the first 60 minutes per month free, then $0.016 per minute with data logging enabled and $0.024 without, and it lists id-ID on both its chirp and chirp_2 models in the asia-southeast1 region. Whisper is MIT-licensed and costs nothing but your own hardware.
At those prices, the recognition itself is close to free. What you are actually buying from any consumer product is everything around it: an upload interface, speaker labels, timestamps, an editor, search across old interviews, summaries, exports, and a place the record still lives in six months.
That is the honest framing of the build-versus-buy question. If you have three interviews a year and can run a Python script, run the script. If you have three a week and need to find a quote from March, you are not shopping for recognition — you are shopping for a filing system with recognition attached.
Four checks matter beyond the free-minute allowance
Minutes and file caps are only part of choosing an interview workflow. Check these four things before relying on any plan, free or paid.
Check speaker diarization on your own two-speaker sample. The table above does not establish which plans include it or how reliably they separate overlapping voices. Confirm the feature and its plan limits, then review the speaker labels; a free-tier label alone cannot answer that question.
Check retention and export rules. A transcription allowance does not tell you how long audio or text stays available, and policies can change. Export important recordings and transcripts and retain your own copy rather than treating a hosted account as your only archive.
Check the recognizer and its performance on your speakers. Regional accents, recording quality, and code-switching can affect the result. A paid plan may offer another model or additional processing, but a higher price is not proof of higher accuracy; rerun the same sample when the engine or workflow changes.
And no tool, free or paid, removes the review pass. An AI summary built on an unreviewed transcript inherits every error in it, confidently and invisibly.
The bottom line: the number to compare is not minutes, it is interviews
Every free tier in this category advertises a quantity of time. That is the wrong unit for interview work, because time only matters if it comes in one continuous piece. One hundred and twenty minutes chopped into three-minute slices is worth less to a journalist than thirty uninterrupted minutes, and both are worth less than sixty minutes that hold a whole conversation with the speaker labels intact.
So when you compare tools, convert every free tier into the only currency that matters to you: how many of my actual interviews does this transcribe, end to end, without splitting the file? For several well-known free plans, the honest answer is zero, and they will not tell you that on the pricing page.
The recognition layer is a commodity heading toward a third of a cent per minute. What remains scarce for Indonesian is a record you can search, correct, quote, and still find next quarter.
Where Telli.sh fits: we are one option among the several above, and we will be specific about it. Telli.sh's Free plan is 60 minutes a month — fewer headline minutes than Notta's 120, and deliberately not sliced by a three-minute per-recording cap, so a full interview goes in as one file. You get the Indonesian transcript, translation into any of 44 target languages, an AI summary generated from the transcript, and an interface available in 15 languages including Bahasa Indonesia. Beyond 60 minutes a month, it is a paid product, and if your volume is low and you can run a script, the API route genuinely costs less. Run the 5-minute test on us the same way you would run it on anyone else.
Sources
- Deepgram, "Nova-3 Adds Armenian, Plus Improved Models for Tamil, Indonesian, and Belarusian", changelog dated August 7, 2026 — improved batch models for Tamil and Indonesian, improved streaming models for Tamil and Belarusian, Armenian (
hy) added for both. - Hugging Face and Voice Arena, "The Open ASR Leaderboard Adds Its First Global South Language", August 28, 2026 — Hindi as the leaderboard's first Global South language.
- Notta pricing, retrieved August 31, 2026 — Free plan 120 minutes/month, 3-minute maximum per recording, 50 file uploads/month, 10 AI summaries/month; Pro $8.17/month billed annually with 1,800 minutes/month.
- Transkriptor pricing, retrieved August 31, 2026 — Lite $9.99/month (300 minutes), Pro $19.99/month (2,400 minutes, $99.99/year annually), Team $30/seat/month (3,000 minutes/seat).
- Maestra pricing and Maestra supported languages, retrieved August 31, 2026 — pay-as-you-go $12 per 60 credits, Lite $23/month for 180 minutes; Indonesian listed for transcription, translation, voiceover, and real-time.
- TurboScribe pricing as captured by the Internet Archive — Free plan of 3 transcripts daily with a 30-minute file cap and single-file uploads; Unlimited at $10/month, $120 billed yearly, 10-hour files. The live page returns HTTP 403 to automated retrieval; treat these figures as directional and confirm on the site.
- Google Cloud Speech-to-Text pricing and supported languages, retrieved August 31, 2026 — first 60 minutes per month free, $0.016/min with data logging and $0.024/min without;
id-IDonchirpandchirp_2inasia-southeast1. - OpenAI API pricing, retrieved August 31, 2026 —
gpt-4o-transcribeat $0.006/minute,gpt-4o-mini-transcribeat $0.003/minute. - OpenAI Whisper, MIT-licensed; the tokenizer's
LANGUAGEStable declares 100 languages with Indonesian (id) at position 17, retrieved August 31, 2026.